

Autonomous Data Products
Agents, Automation, and Humans: Drawing the New Lines of Enterprise Work
This is a recap of the September 23rd Nextdata webinar with Zhamak Dehghani, the first session in our AI-Native series.
Thank you to everyone who joined our live session Agents, automation, and humans: Drawing the new lines of enterprise work
Every enterprise wants agents as a workforce multiplier. Few have a clear model for deciding which parts of a job an agent should do, which parts should be plain code, and which parts still need a person. Zhamak shared what Nextdata's forward-deployed engineering teams have learned working with large, complex organizations. They are not just refreshing their data and AI stacks. They are redesigning how work gets done.
Autonomy, speed, and safety: finally within reach
Zhamak opened with the three outcomes Nextdata has always worked toward:
- Autonomy: people closest to the work can build and change it, without waiting on a central team's backlog.
- Speed: the path from idea to outcome gets dramatically shorter.
- Safety: that autonomy holds up at enterprise scale.
Her argument is that the current generation of AI is the missing piece that makes this combination practical.That raises a simple-sounding question: if we're changing the nature of work, who or what should do the work, and how should the work be redesigned?
The promise, and the new problems
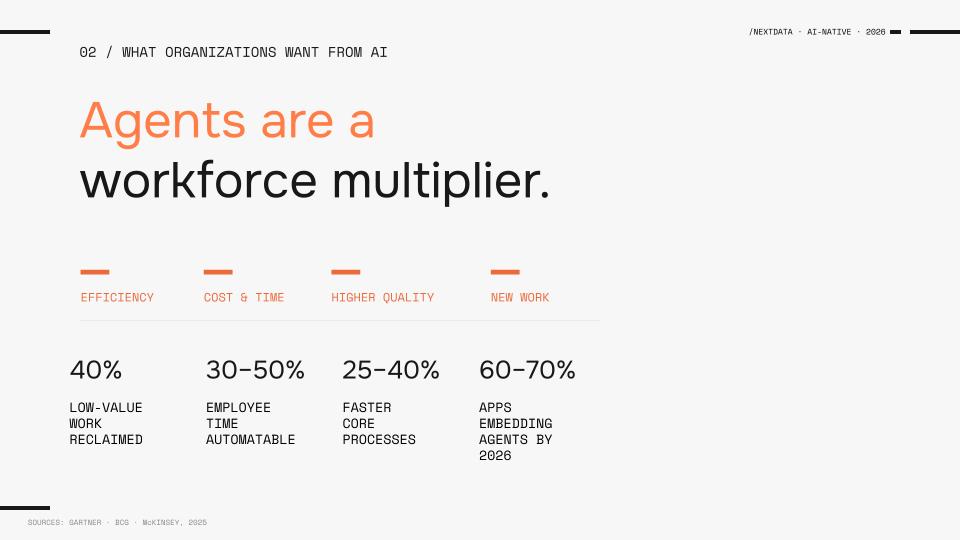
Organizations want what you'd expect from agents: greater efficiency, lower cost, faster outcomes, and higher quality. Most of all, they want to do jobs that used to be inconceivable because the cost or time was too high.
Zhamak grounded the session in one running example: an engineering manager hiring AI-native engineers. With AI, that manager can do what a generic applicant tracking system never could, such as analyzing each candidate's public GitHub contributions and technical writing to find people genuinely suited to the role.
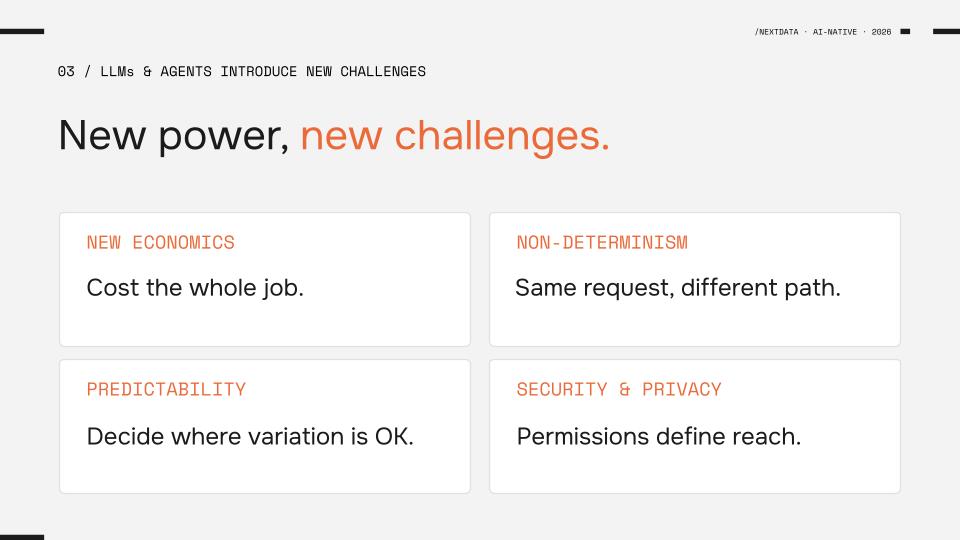
Handing that whole process to agents introduces four new challenges:
- New economics. The cost of a job now includes tokens, tool calls, and multiple exploratory paths toward the same outcome.
- Non-determinism. The same request can produce different answers, which is jarring for people used to software that behaves the same way every time.
- Expectations of predictability. Enterprises want the flexibility of LLMs and consistent results, so someone has to decide where variation is acceptable and where it isn't.
- Security and privacy. Agents need access to data and tools, and permission to change the state of the business. That power cuts both ways.
The answer, Zhamak said, is deceptively simple: be deliberate about how work is allocated between agents, humans, and code. And don't forget code. Coding agents can now turn an exploratory LLM session into predictable, reliable software.
Framework 1: The AI-native job automation cycle
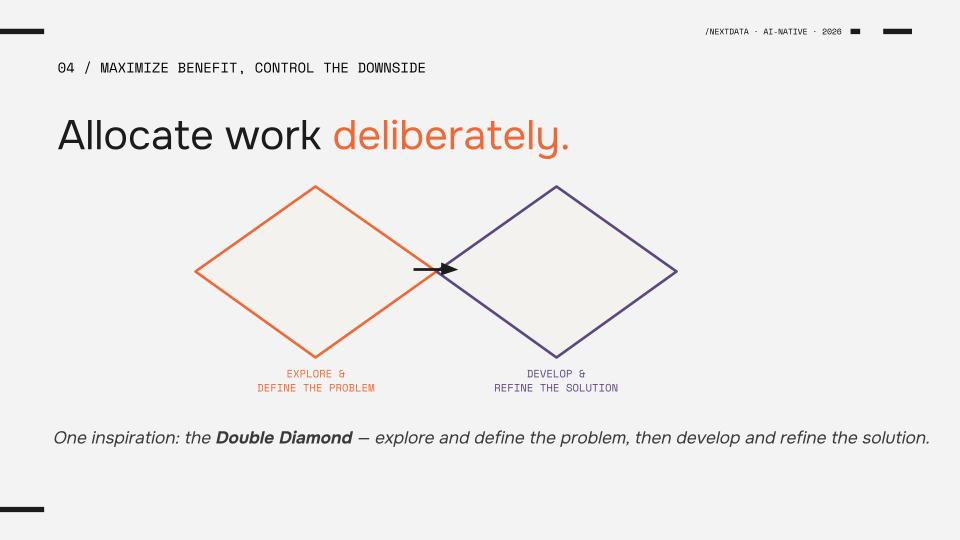
Zhamak drew on a lesson from the last major transformation, the move from brick-and-mortar to digital, when product teams adopted the Double Diamond's pattern of divergent exploration followed by convergent delivery.
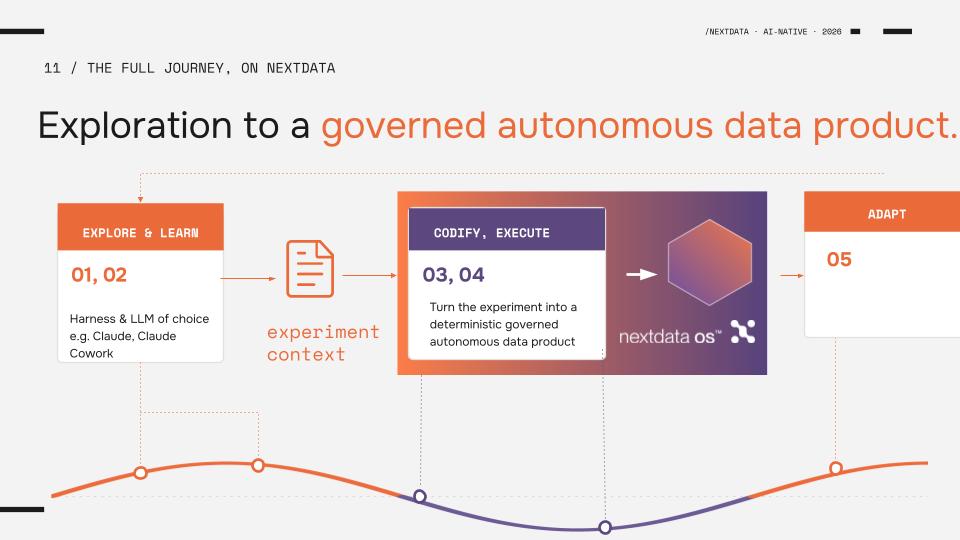
The AI-native job automation cycle adapts that idea. Picture a wave: the vertical axis is LLM involvement. Higher on the curve means more inference, more non-determinism, and higher token cost. Lower on the curve means explicit rules, well-defined execution, and economics that look like a traditional application.
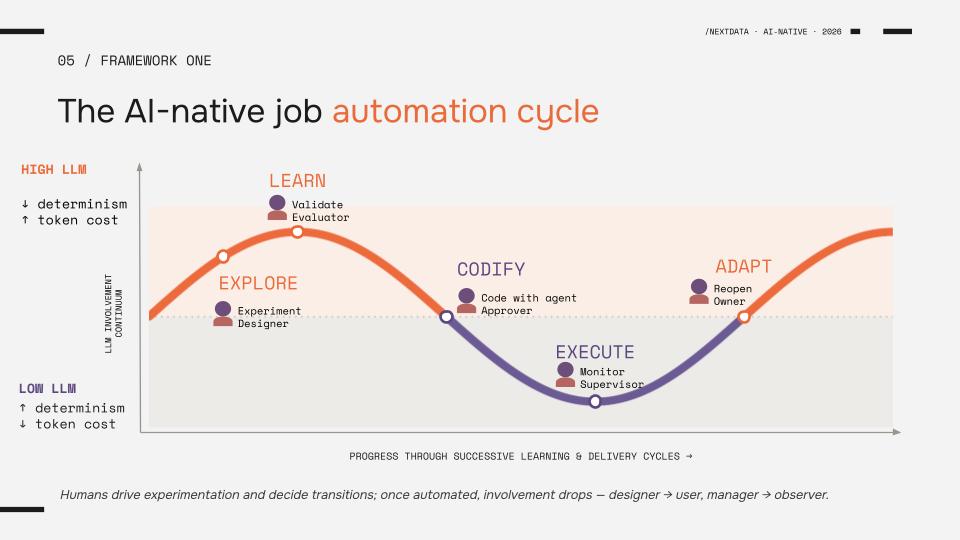
Work oscillates through five phases:
- Explore. LLM-intensive. You try approaches, have long conversations, and burn tokens, but the stakes are low.
- Learn. At the crest, useful patterns emerge. You now know what the dashboard should show or what intelligence you need to make a call.
- Codify. A coding agent turns that session into repeatable code. That code may use an LLM for some steps, or none at all.
- Execute. The process runs as part of your operational stack, with predictability and controlled cost.
- Adapt. When requirements change, you go back to exploration and the cycle repeats.
Many organizations struggle because they conflate these phases. They vibe-code something for themselves and then try to make it the operating fabric of the organization, without the codification step.
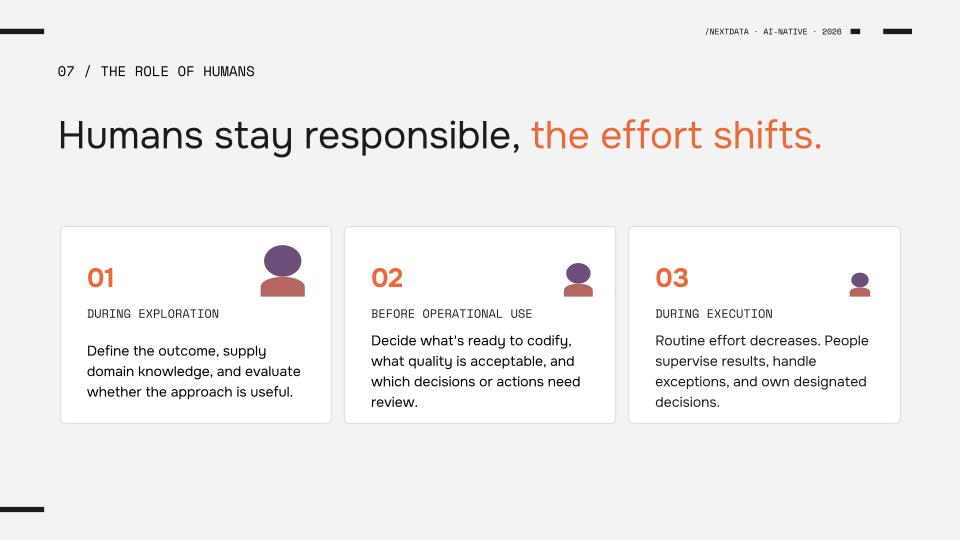
The human role changes across the cycle as well. People drive during exploration, make judgment calls while learning, direct the coding agent during codification, monitor during execution, and decide again when it's time to adapt. Over the cycle, humans shift from designers of the work to managers of it.
The cycle in practice
The hiring example is real. A few months ago Nextdata posted a job and received 300 applications in 24 hours. No ordinary process could keep up, so we automated it in a few hours.
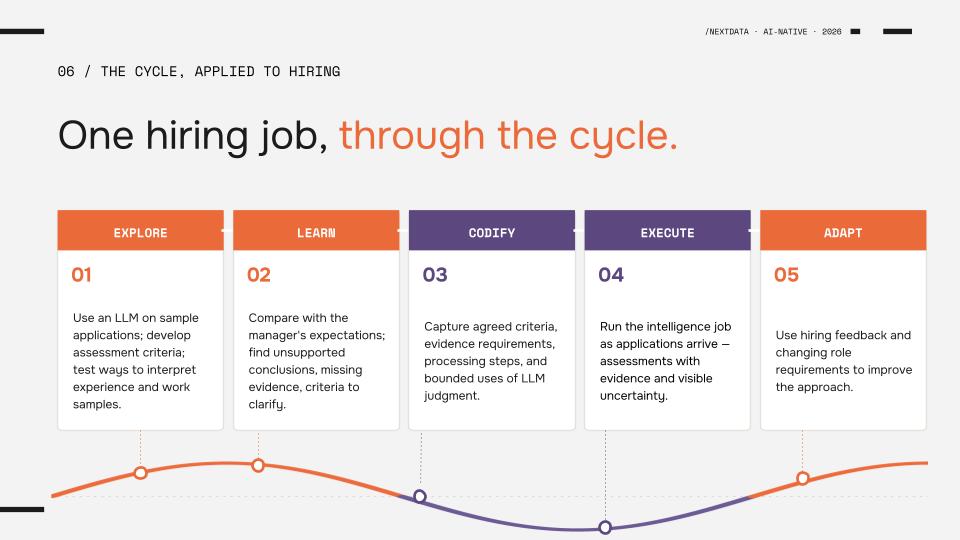
She began in Claude, exploring a sample of candidates to build scoring criteria for her situation: a startup looking for zero-to-one engineers who contribute to open source. Along the way she found things no off-the-shelf tool would catch, such as candidates who had copied other people's repositories without forking or attribution.
Once the scoring and gating logic was solid, she handed the session to a coding agent. The resulting application uses deterministic code where it can, for example to convert resume PDFs into structured data and score experience. It keeps LLM inference to a tightly scoped task: judging the quality of a GitHub repo. Every new application gets scored automatically. When her criteria change, she goes back through the loop.
Framework 2: AI-native job design
The automation cycle explains how to automate. It doesn't say what to automate. Here Zhamak named a common anti-pattern: sprinkling agents on top of existing workflows.
Those workflows were designed under old assumptions about the cost of automating a task, the cost of observing it, and where human judgment was actually required. Those assumptions no longer hold.
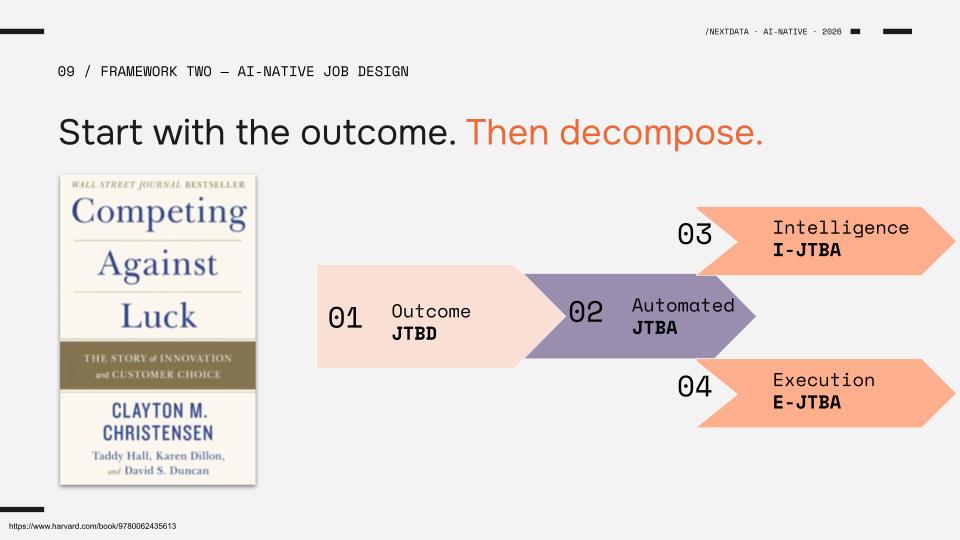
She drew on another lineage. Theodore Levitt's observation that people don't want a drill, they want a hole, later grew into Clayton Christensen's jobs to be done. Reviewing resumes, scoring candidates, and booking interviews are steps. The job is getting the right engineer onto the team.
Zhamak extended the idea from jobs to be done (JTBD) to jobs to be automated (JTBA):
- Start with the outcome. Bring the right AI engineer onto the team.
- Work backward to redesign how agents, LLMs, code, and people achieve it.
- Decompose into two kinds of jobs:
- Intelligence jobs produce information for people or agents: gathering evidence on candidates, scoring them, and preparing interview questions. They have no side effects.
- Execution jobs change the state of the business: scheduling interviews, sending approvals, declining applicants.
That boundary is the design decision that matters most. Intelligence jobs capturelet you get the full benefit of LLMs and agents, while keeping the right to act on, and to commit the business stays, with humans for as long as you choose.
Autonomous data products are intelligence jobs
Nextdata has spent years building autonomous data products for organizations, and they are exactly this kind of job.
In the hiring example, an applicant-scoring data product continuously listens to the applicant tracking system's API, pulls from the web and candidates' public repos, and produces a scored, live, historical view of candidates. Controls are built in: candidate information stays restricted to the people who should see it, and quality checks make sure scoring behaves as expected and no data is lost. Much of it is simple Python. LLM inference happens only in the product's kernel, where it's needed.
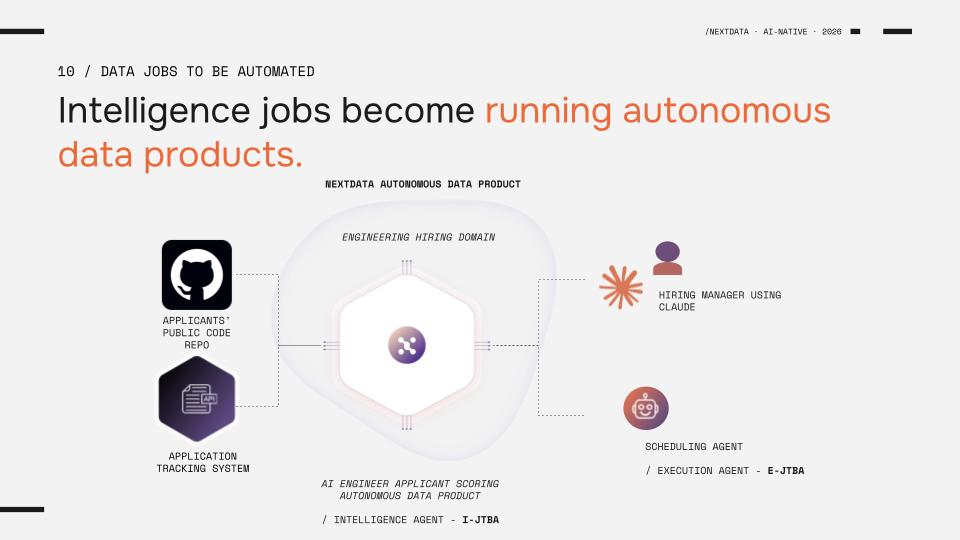
Downstream, that product can serve a human asking Claude for today's top candidates, or an execution agent that schedules everyone above a threshold. Either way, most of the automation effort lives inside the intelligence layer, where the data is useful, traceable, and always available.
Zhamak contrasted this with what one prospect described as their current approach: an HR-embedded data engineering team building a pipeline, moving data into a warehouse, and cataloging it. "I was falling asleep as he was describing it," she said. It's a paradigm that no longer fits where we are with AI.
A preview of what's coming
Zhamak gave a brief preview of upcoming product announcements. The workflow will look like this: explore in Claude or the agent harness of your choice, connected to your systems through MCP. When you reach a good result, ship that session's context to Nextdata. Nextdata creates and runs the autonomous data product and gives downstream agents and humans direct access to it. When the process needs to change, Nextdata gives you the right context to go around the cycle again.
Full demos are coming in future sessions.
What this means for the AI-native organization: autonomy
Data mesh established that domains should own their data, supported by self-serve platforms with computational governance built in. AI now extends that autonomy from data to the work itself, including in organizations that never had the people or resources to do it before.
The organizational shift:
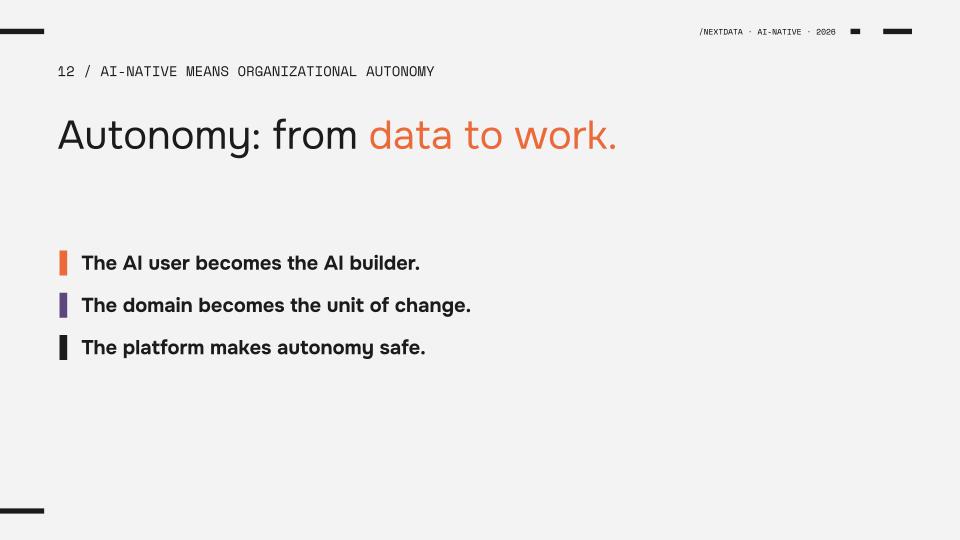
- From requesting a solution and waiting in a central backlog, to building it yourself.
- The hiring manager becomes the product owner of hiring intelligence.
- The platform makes autonomy safe and scalable. In Nextdata OS, controls, permissions, scheduling, runtime, and observability are packaged into the data agent itself.
- Responsibility stays close to the outcome. The domain owns the automation, the quality, and the result.
- AI users become AI builders. Generic SaaS tools become systems of record, while the intelligence and automation unique to you run on your platform, to your design.
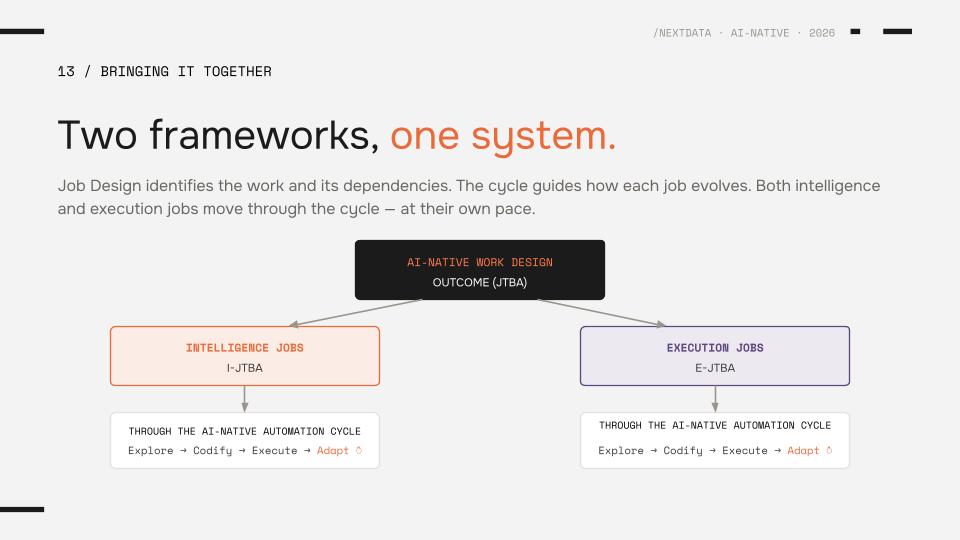
Bringing it together
The two frameworks combine into one system:
- Design the job from the outcome. Decompose it into intelligence jobs and execution jobs.
- Run each job through the cycle, spending LLM effort where exploration pays off and codifying the rest.
- Let people set the boundaries. Humans establish the outcome, evaluate quality, and decide deliberately how much to delegate.
Up next: A semantic interface for intelligence
One lesson from building autonomous data products is that the industry lacks a standard interface for exchanging meaning, so that humans, Claude, or agents can interact with data products semantically rather than syntactically. Nextdata has been standardizing that interface on every data product built on Nextdata OS, extending MCP with semantic discovery, understanding, and query. It is built on a decentralized, API-based model rather than a centralized warehouse.
The next session, on October 7th at 9 AM PT, will look under the hood. Sessions run every other Wednesday. Register to join us live or to make sure you get the recording.
If you'd like to talk with us about redesigning work around autonomous data products, book a meeting with us.
More resources
If you missed the Nextdata Product Update: Data 3.0 - Domain-Oriented Semantic Context for AI Agents, you can watch the webinar recording here.
Also see how Data 3.0 makes enterprise data truly AI-ready you can reply Data 3.0 in action: What we showed at the Nextdata OS product update
And if you’re ready to see how Nextdata OS implements these shifts in your own environment, request a sandbox or get in touch at sales@nextdata.com


